Scroll to open the possibilitiesExplore what you can build
The release / October 2026Built for work beyond chat.
One API. More room to build.
Pareto blends models behind one API. 26.10 brings a 1M-token context window, tool calling and lower token rates for your next feature, agent or research workflow.
The creator reports working thumbnail generation after fixing application state. The build shows Pareto being used to develop a creative application.
Built with Union Alpha, later revealed as Pareto 26.9—not a 26.10 result. Stripe billing remained unfinished. The video discloses Bright Data sponsorship.
1,025,368 recorded output tokens · output-only estimate
Pareto 26.10$3.28Your baseline
GPT-6.1 Sol$10.253.1× Pareto
Claude Opus 5.5$20.516.3× Pareto
Claude Fable 5.1$51.2715.6× Pareto
GPT-6 Astra$51.2715.6× Pareto
How this comparison works
Output-only estimates at standard-context API rates, not total build costs or rebuild quotes. Input and cache charges excluded. The $35.23 above is the builder’s reported historical spend, not this calculation. Claude rates · OpenAI rates · Build account.
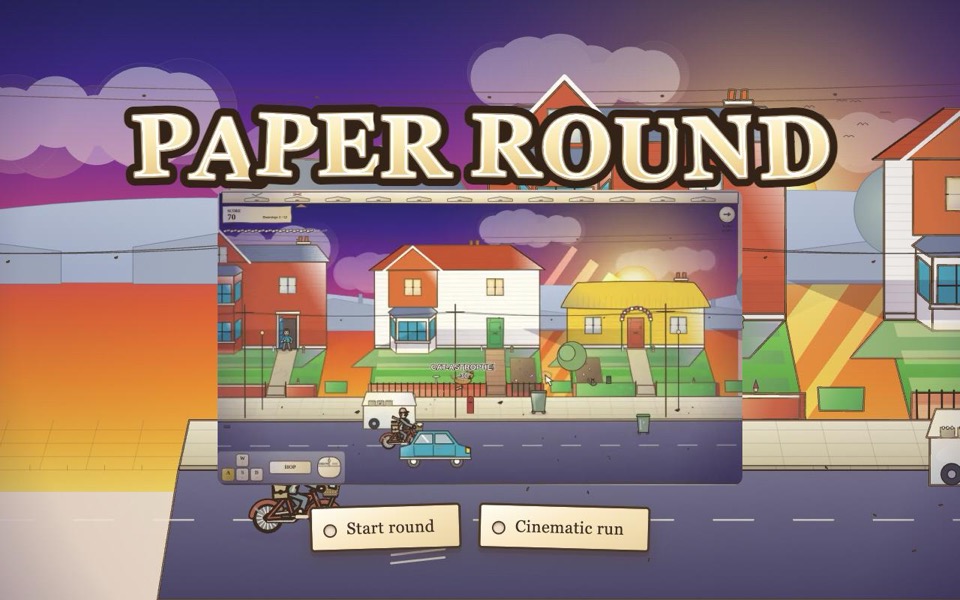
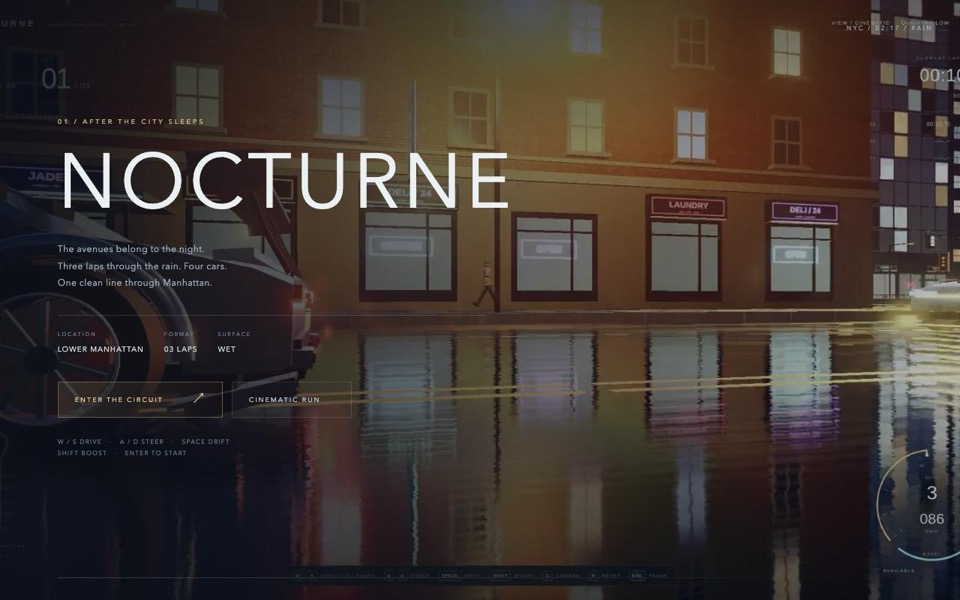
An illustrated street game. Jump in and start a round.
$12.1558 model calls Reported model cost
Same output. A different bill.
Pareto: 68–94% less
629,903 recorded output tokens · output-only estimate
Pareto 26.10$2.02Your baseline
GPT-6.1 Sol$6.303.1× Pareto
Claude Opus 5.5$12.606.3× Pareto
Claude Fable 5.1$31.5015.6× Pareto
GPT-6 Astra$31.5015.6× Pareto
How this comparison works
Output-only estimates at standard-context API rates, not total build costs or rebuild quotes. Input and cache charges excluded. The $12.15 above is the builder’s reported historical spend, not this calculation. Claude rates · OpenAI rates · Build account.
This prototype used Pareto 26.10 Preview and Claude assistance. It is not an isolated model evaluation.
YFarmX reports these model costs and call counts for builds made with Pareto 26.9. Costs are not independently audited and exclude other project costs. Paper Round included final fixes by hand. Read the build accounts.
From the community
What the community is sharing.
Python Coding@clcoding
𝕏
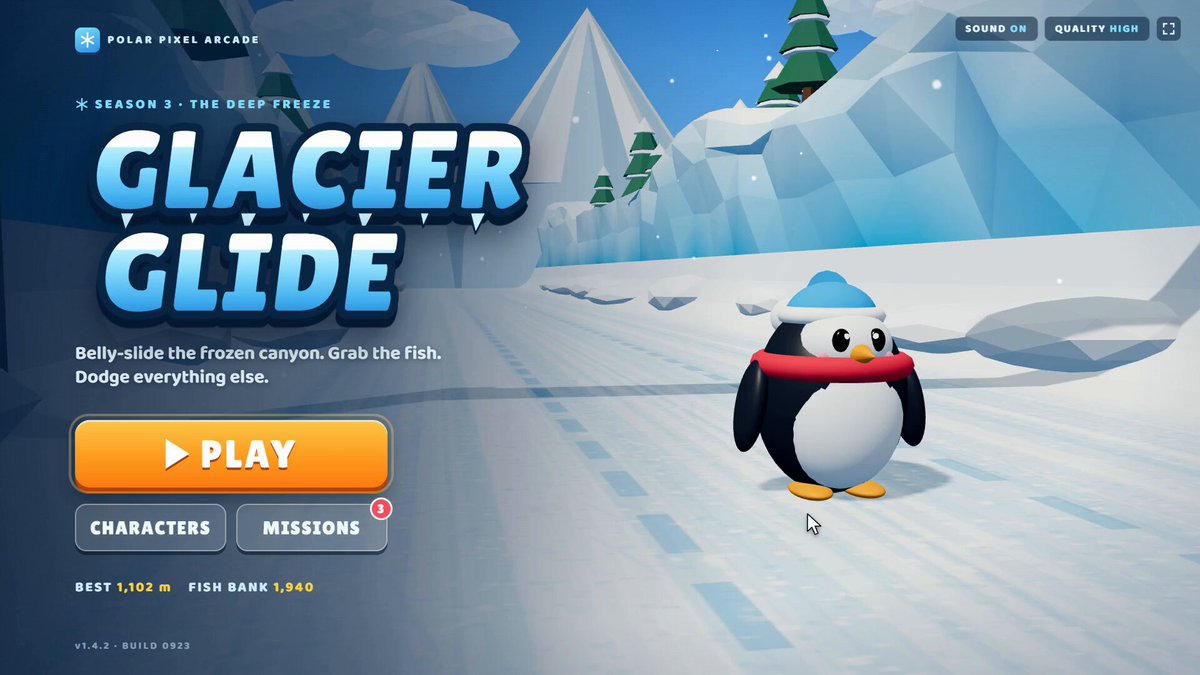
Still, as a full autonomous game generation, this is a strong result. Pareto 26.9 is definitely interesting.
Santiago@svpino
𝕏
This pareto-26.10-preview model is pretty cool. It does something I haven't seen before:
OpenRouter@OpenRouter
𝕏
A multimodal composite model for research, coding, and agentic workflows, with 1M context, text and image input, and tool calling.
02 / Put Pareto to workStart with your task.
What will you do with Pareto?
Ask a question in Chat, connect your business tools, or build with the API. Choose where to start.
For everyday work
Get from information to a decision.
Compare proposals, work through a difficult question, or turn your notes into a clear first draft.
Start without codeBring a real question to Pareto in Chat. Review the answer and check its sources.
03 / The resultPreliminary · October 1 preview measurements
The result. And what it cost.
Useful for your next patch, tool run or hard question? Start here. Then test Pareto on the work you actually do.
In preliminary October 1, 2026 preview results, Pareto 26.10 Preview matched or set the Pareto frontier on all four benchmarks.
01 / What this tests
DeepSWE v1.1
Working through software-engineering tasks in a codebase.
Agent harness and execution setup matter.
Preliminary score69.9%
Cost per task$0.24
DeepSWE v1.1 · 69.9% · $0.24/task
0%This test only100%
02 / What this tests
Terminal-Bench 4.0
Completing tasks through a terminal environment.
Results depend on the agent harness and execution setup.
Preliminary score50.8%
Cost per task$0.48
Terminal-Bench 4.0 · 50.8% · $0.48/task
0%This test only100%
03 / What this tests
HLE text-only
Answering challenging questions across academic subjects.
Text-only subset; not the full multimodal exam.
Preliminary score49.9%
Cost per task$0.008
HLE text-only · 49.9% · $0.008/task
0%This test only100%
04 / What this tests
GPQA-Diamond
Answering graduate-level science questions.
Diamond subset, not a general-purpose accuracy score.
Preliminary score92.4%
Cost per task$0.004
GPQA-Diamond · 92.4% · $0.004/task
0%This test only100%
Four separate tests, not one shared quality scale. Select a card for evaluation context.
All four results / exact numbers
Pareto 26.10 Preview preliminary benchmark scores and task costs, October 1, 2026
Benchmark
Score
Cost / task
Software engineeringDeepSWE v1.1
69.9%
$0.24
Terminal tasksTerminal-Bench 4.0
50.8%
$0.48
Humanity’s Last ExamHLE text-only
49.9%
$0.008
Graduate-level scienceGPQA-Diamond
92.4%
$0.004
Preliminary October 1, 2026 preview measurements, not new release measurements. These are not estimates for your workload. Each chart runs from 0 to 100% for its own test; scores across different tests are not directly comparable.
Sources and evaluation scope
Competitor rows in the release come from external publications, not a controlled head-to-head. Published results use different harnesses. DeepSWE v1.1 and Terminal-Bench 4.0 results depend on the agent harness and execution setup. HLE is the text-only subset; GPQA is the Diamond subset.
Sol and Astra: standard-context estimate, not suitable for long-context requests.
Pareto 26.10$1.56
Pareto 26.10: $1.56 estimated API cost
Opus 5.5$8.80
Opus 5.5: $8.80 estimated API cost
Sol 6.1$4.40
Sol 6.1: $4.40 estimated API cost
Fable 5.1$21.00
Fable 5.1: $21.00 estimated API cost
Astra 6$24.00
Astra 6: $24.00 estimated API cost
Shared bar scale: $0–$24.00
Pareto 26.10 $1.56; Opus 5.5 $8.80; Sol 6.1 $4.40; Fable 5.1 $21.00; Astra 6 $24.00.
Pricing sources and calculation details
Standard API service, USD rates checked October 15, 2026. Each estimate = uncached input × input rate + cache reads × read rate + billed output × output rate; volumes are in millions. Bars share a zero baseline and one scale; values are rounded to cents.
Cache reads only: no cache-write charges are represented. If you have nonzero cache writes, include their charges separately using the provider’s write rates; do not count them as reads or ordinary input. This is not an all-in bill. Excludes tools, hosting, taxes, human review, batch, fast-service and regional pricing.
The context selector changes only Sol and Astra rates, manually. Select the provider’s applicable per-request tier; aggregate token volumes do not determine it. For a mix of tiers, calculate each group separately. The exact 272K threshold boundary has not been verified here, so this calculator never selects it automatically.
Same numeric token volumes do not guarantee the same text, quality or outcome. Tokenizers, reasoning, retries and strategies change usage. The games’ published usage is incomplete and caching is unknown; these estimates are not quotes to rebuild them. No live inference or network calls run in this calculator.
USD per 1M tokens · selected tier · estimated total
Unbiased API · current defaultparetoPin the stable releasepareto-26.10API setup and docs
1M context window. Tool calling. On the Unbiased API, pareto now points to 26.10; pareto-26.9 remains available. The pareto-26.10-preview ID is being retired: switch to pareto or pareto-26.10. Test your workload before switching. OpenRouter availability is listed in its provider catalog.



 Watch the build ↗